Operations | Monitoring | ITSM | DevOps | Cloud

Evaluate your AI agents with Fireworks AI models in Datadog Agent Observability

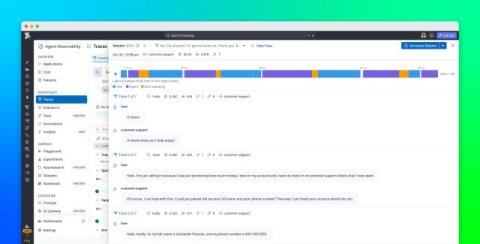
Teams that build agents on open models hosted on Fireworks AI, such as GPT-OSS, Kimi, GLM, Qwen, and MiniMax, need a reliable way to measure whether their LLM applications and agents are giving accurate, safe, and helpful answers efficiently. Datadog Agent Observability now supports Fireworks AI as a model provider, so you can get end-to-end visibility into your agents built on Fireworks AI, from traces and token usage to quality evaluations.
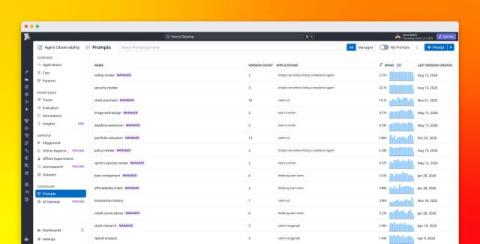
Manage and deploy LLM prompts with Datadog

Prompts are an important part of LLM application behavior, but teams often manage them alongside application code or across separate notebooks and configuration files. This can make prompt changes dependent on application releases and make it difficult to understand which version is running in each environment. When a change affects application quality, latency, or cost, teams also need a way to connect that behavior back to the prompt version that produced it.

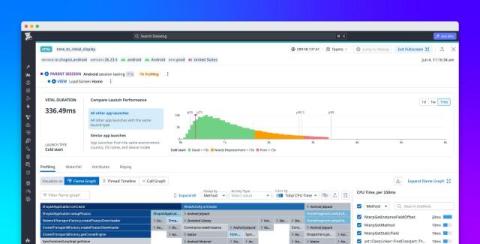
Diagnose frontend performance issues with RUM Profiling

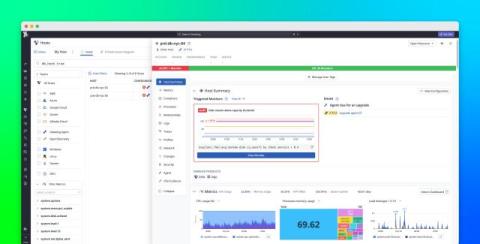
When a mobile application takes too long to launch or becomes unresponsive, it can be difficult to find the cause. Datadog Real User Monitoring (RUM) helps developers detect these issues and understand which users are affected. But knowing that an application is slow doesn’t tell you which part of its code is responsible. Engineers often need to reproduce the problem locally, piecing together performance metrics and code execution information from separate tools.

How we use Insights to improve the agent behind Insights

Improving an AI agent means knowing which behaviors to change and where those changes will have the greatest impact. Insights in Datadog Agent Observability improves AI agents by analyzing agent traces to identify recurring cost and reliability problems. It then explains the causes of those problems, assesses their impact, and recommends fixes backed by evidence. At Datadog, we use Insights to improve the agent behind Insights.

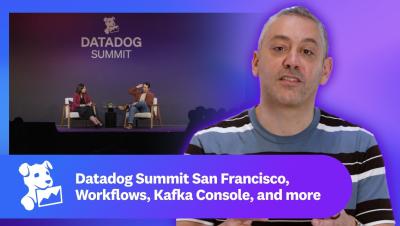
Datadog Summit San Francisco, Workflows, Kafka Console, and more | This Month in Datadog

October’s This Month in Datadog comes to you from the Datadog Summit in San Francisco, where Jeremy shares a look inside the event, with our latest product updates. Plus, we cover how to: Build and manage Datadog Workflows using natural language, turning descriptions of automation tasks into workflows that teams can review before publishing Detect and investigate Kafka issues with Kafka Console, bringing health and performance data into one place Turn raw logs into structured fields with Datadog Tap, making logs easier to search and analyze.

Detect when your AI agent copies a self-replicating prompt injection

In September 2026, OpenAI reported finding self-replicating prompt injections. These attacks hide instructions in content an AI agent retrieves, directing it to take unauthorized actions and copy those instructions into emails, files, or messages. Copied instructions can then expose other agents or later sessions to the same attack, giving it the potential to spread like a computer worm.

Datadog named a Leader in the Forrester Wave: AIOps Platforms, Q4 2026

Datadog has been named a Leader in The Forrester Wave: AIOps Platforms, Q4 2026. We believe this placement reflects Datadog’s commitment to transforming observability into autonomous operations with a single integrated platform where AI agents detect, investigate, and remediate production issues, while engineers stay in control. Close dialog.

Trace voice agents with Datadog Agent Observability

A voice agent can return the right words and still deliver a poor experience. It might leave a caller in silence, speak over them, or stop midway through a response. A transcript may look correct even when the audio the user heard was delayed, incomplete, or different from the text on screen. These problems are difficult to diagnose from text traces alone. Voice conversations also involve more than a single request and response.

Default to serverless for AI agents, then let production data decide what moves

Serverless should be the first execution model teams evaluate for AI agent workloads. Many agents spend much of their lifetime waiting, and always-on compute forces teams to pay for every idle minute. In a study of more than 35,000 production coding-agent sessions, the median session ran LLM or tool calls for only 20% of its lifetime. The rest of the time, it sat idle between steps, with its sandbox still allocated.

Match monitoring depth to workload needs with Infrastructure Basic

A back-office server that runs out of disk space can interrupt an important internal workflow. A process that stops on a staging host can delay development. Although workloads like these might not require application-level instrumentation, teams still need to know when the hosts that support them require attention. Without a monitoring solution tailored to these requirements, teams have to apply more monitoring than the workload needs, maintain a separate tool, or accept a gap in visibility.