Operations | Monitoring | ITSM | DevOps | Cloud

Stop Adding HR Tools. Start Using the Platform You Already Have | Atlassian Webinar

Tired of spreadsheet trackers, lost Slack requests, and SaaS sprawl? Learn how to turn your existing Atlassian stack—Jira, Confluence, and Jira Service Management—into a unified HR hub for recruiting, zero-touch onboarding, and compliance. Most companies run on Atlassian, but HR workflows often remain scattered across spreadsheets, endless email threads, and disconnected SaaS tools. The answer isn't another point solution or a costly rip-and-replace—it's connecting the systems you already have.
Is VPA "Good Enough"? How Kubex Delivers Enterprise-Ready Workload Optimization

Kubernetes workload rightsizing is one of those tasks everyone agrees is important and almost nobody enjoys doing by hand. Set requests too high and you pay for capacity that sits idle; set them too low and you invite CPU throttling, out-of-memory kills, and late-night pages. It’s no surprise, then, that many teams reach for the Vertical Pod Autoscaler (VPA) as their first step toward automated rightsizing.

Data Center Rack Density Just Crossed 11kW. Do You Have the Tools and Data to Keep Up?

Uptime Institute's Global Data Center Survey 2026 found that the average modal rack density exceeded 11 kW in 2026, up from 9 kW in 2025. “Modal rack density” means the rack density that is most common within a data center. Arguably, the more important trend is that rack densities are becoming more varied, with more facilities supporting a mix of conventional and high-density racks.

CVE-2026-74580: Possible VM Escape via the Vghost Vulnerability

CVE-2026-74580 is a high-severity Linux kernel bug in vhost, the subsystem that accelerates I/O for virtual machines. It gives a local user a reliable path to root on the host, and in some VM setups it lets a guest write into host memory. The CVE record has existed since August 21, 2026, but the full technical write-up, nicknamed "Vghost", only went public on October 12. It came with working exploit demos for both a local root escalation and a VM escape.

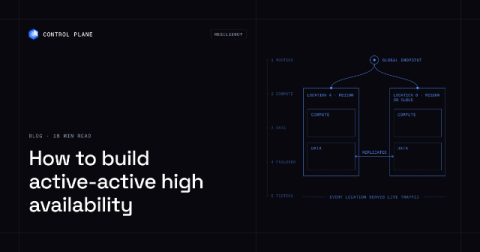
How to Build Active-Active High Availability Across Regions and Clouds

Active-active means two or more locations serve live traffic at the same time, with the application running in each and its data replicated across them, so no location sits idle waiting for a failover. You build it in five layers, and data is the hardest.

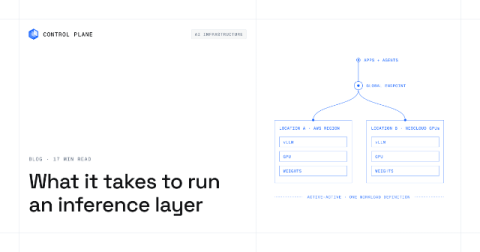
What Infrastructure Do You Need to Run an Inference Layer? A Production Guide

A production inference layer needs GPU compute sized to the model, a serving runtime such as vLLM or SGLang, orchestration that autoscales on queue depth, one endpoint with health-aware routing and failover, model weights cached near the GPUs, and observability, security, and cost controls.