Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Cloud monitoring, security and related technologies.

Before your AI bottleneck gets worse: what to put in place now

Your engineers have agents running. Not one agent, but several, spread across the team. Some run in a terminal on a laptop, some are wired into your CI jobs, and some live inside whatever coding tool each person prefers. Each one got set up separately, by whoever needed it, in whatever way worked that week. That is the state most teams are in right now. Code stopped being the slow part a while ago.
Shipped: Don't ask an AI agent what its work will cost

If you set the budget for your team’s AI agent work, or answer to someone who does, you need a rough idea of what a job will cost before it starts. That’s hard to get. Stanford researchers found the same agent, given the same task, can use up to 30 times more tokens from one run to the next, and you usually find out afterward. Most developers just run the job.

Cost per AI outcome: tying AI spend to results

Cost per AI outcome is your total attributed AI spend divided by the business results it produced: resolved tickets, converted leads, merged pull requests. It includes the cost of failed attempts, sits at the top of the AI unit-cost ladder, and it's the number that makes vendor outcome pricing, ROI claims, and build-versus-buy decisions comparable.

What platforms support container auto-scaling and policy-driven resource management?

Table of Contents Autoscaling and policy-driven resource management are two sides of the same coin. Autoscaling adjusts capacity as demand changes, while policies define the boundaries it operates within: who can use how much, which workloads can be changed, and what safeguards must be respected. Without autoscaling, clusters are either overprovisioned or overwhelmed. Without policies, autoscaling can create runaway costs, noisy neighbors, or disruptive changes to critical services.

What tools detect and resolve Kubernetes resource contention automatically?

Table of Contents Resource contention happens when workloads compete for more capacity than a node or cluster can provide. For CPU and memory, the symptoms are familiar: CPU throttling, OOM kills, and noisy neighbors slowing latency-sensitive services. These are largely solved problems, addressed by accurate requests and limits, Quality of Service classes, and autoscalers like VPA and HPA that adjust sizing and replicas as demand changes. GPU contention is different, and far more expensive to get wrong.

How to Make an Email Without a Phone Number with Internxt Mail

Creating an email account usually seems simple until you’re asked for a phone number. If you’d rather keep your number private, don’t have access to one, or simply want to keep your accounts separate, you may be wondering if there’s another option. The good news is that Internxt lets you create an account without phone verification with an Ultimate Internxt plan, or create temporary emails for free with no phone number or other personal details required.

AI Agent Infrastructure: Where to Run Agents in Production

Run production AI agents on infrastructure with hardware-level isolation, sub-second sandbox restarts, and a compliance posture that already covers PCI DSS, HIPAA, and GDPR, so a single misbehaving agent can’t touch another workload or your audit trail. Control Plane runs every agent workload in a Kata Containers sandbox on a per-workload Firecracker microVM, with Capacity AI packing resources and scaling workloads dynamically to cut compute cost 30-50%.

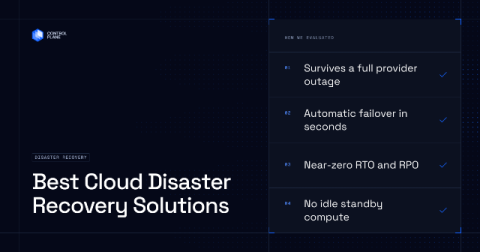
Best Cloud Disaster Recovery Solutions for 2026

Most disaster recovery plans are designed to survive infrastructure failures — a zone goes down, a region becomes unavailable — but assume the cloud provider itself stays up. That assumption fails more often than engineering teams expect, and when it does, the gap between a team that keeps running and a team writing incident reports isn’t luck: it’s whether DR was an architectural default or a runbook nobody has tested.

Cycle and Cherry Servers Webinar: Sovereign Bare Metal with Cloud Simplicity

Cycle teamed up with bare metal service provider Cherry Servers to discuss how rising political tension and controversy involving the United States is pushing many European organisations to take a closer look at where their data is hosted and handled. Many companies have been forced to look into alternative options to ensure their data is not hosted in or accessible by anyone outside of Europe.