Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on API Development, Management, Monitoring, and related technologies.

Test Behavior, Not Choreography

The spy from post 4 is a sharp tool. Once a test can record every interaction, it is tempting to assert on all of them. The result looks thorough, but it is usually a transcript rather than a useful specification. This post takes a test written that way, makes a change that no customer could possibly notice, and watches the test fail anyway. This is part 5 of a ten-part series. The code is in Java, Node.js, Go and Python.
CRM API Rate Limits: What Developers Need to Know Before They Build

Every CRM integration starts the same way. You write some code, test it against a sandbox account with a few hundred contacts, and everything works beautifully. Then you push to production, where the account has 50,000 records and three other integrations pulling data at the same time, and suddenly you're drowning in 429 errors.

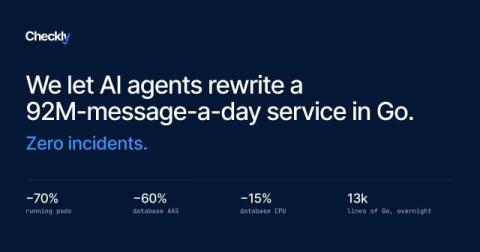
We Let AI Agents Rewrite a 92M-Message-a-Day Service in Go. Zero Incidents.

Our Results Daemon processes about 92 million messages a day. We recently rewrote it from Node.js to Go, and we let Claude Code write it. We wanted to know whether we could trust an agentic rewrite for a critical, high-throughput production service rather than a prototype. It shipped with zero incidents, a 70% reduction in running pods, and a lighter database load.

Your Observability Stack Found the Fire. Congratulations.

The dashboards are red, the alerts are firing, and Slack has officially become a war room. Someone has asked, “Anyone else seeing this?” and 14 people have immediately responded with screenshots. Welcome to another day in distributed systems. The recent GitHub outage is a great reminder of how complicated modern applications have become. Services talk to services, infrastructure scales up and down, retries multiply traffic, and dependencies behave in ways nobody expected.

The Compounding Platform Tax

Private cloud and on-premises infrastructure are different. I know this. I used the terms interchangeably anyway because I was trying to compress a pattern into one sentence. That was sloppy, but the underlying pattern still matters. Banks run Kubernetes differently from most other organizations. Not because every bank makes the same choices, but because similar constraints can produce a similar pattern.

Shipped: API keys that keep their own permissions current

The most common reason to create an API key in CloudZero is to send data, such as AI telemetry or billing exports. Until now, that meant picking individual scopes from a list and hoping you chose the right ones. That works on day one. The problem is day ninety. Permissions on a key have always been a snapshot of the day you created it. A new AI telemetry endpoint ships in October, and a key created in August has no idea it exists.

Application Level Dependency Chaos Testing

Somewhere in your service is a branch that has never executed. Not a rare one, a never one. It handles a dependency being unavailable: it reads from a cache, it returns a stale value, it marks the response degraded so callers know not to trust it too far. It was written carefully. It was reviewed. Whether it works is an open question, because nothing in the test suite makes that dependency fail, and the dependency does not fail on request.

Break One Dependency, Not The Whole Cluster

Scoped chaos rules are now in proxymock. A filter query picks the traffic, an effect perturbs it, and every response that gets touched is labelled so you can tell an injected failure from a real one for the rest of the run. Available in v2.5.892 and newer. The short version of why: kill a pod and you learn something real, but you do not learn what your service does when a dependency stays up and starts lying to it.

I built an API traffic classifier for business workflows

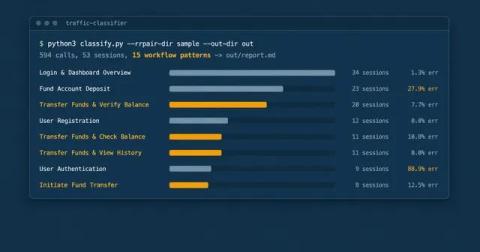
An engineering leader asked me a question a few weeks ago: could we read their business workflows out of API traffic instead of asking people to document them? I said it should be possible. Then I tried it. A few engineers know how the system really works. They know which calls make up a work order and which checks happen after a write. That stuff rarely makes it into the test plan. Usually it’s in somebody’s head. Sometimes it’s in several heads, with slightly different answers.