Operations | Monitoring | ITSM | DevOps | Cloud

What Is Agentic Operations and Why Ops Teams Are Adopting It

AI coding tools have changed how fast software ships. They haven’t changed who runs it. Every extra release, alert and incident still lands on the same SRE, Platform and DevOps teams, and 78% of technology leaders report more incidents since adopting AI-generated code. So operations teams are turning to agents too. Six in 10 enterprise leaders are piloting, deploying or evaluating automated incident response, according to Caylent.
Agent Observability FAQ: Understand the value of monitoring, evaluating, and improving your AI agents

Agents have quickly become part of the tech landscape as organizations embrace AI across their businesses. But embracing agents also means embracing the monitoring best practices that have long been part of engineers' workflows: tracking performance, catching errors, and responding to incidents But it doesn't stop there. Agents also introduce new challenges.

Building a local AI agent in Workshop on Ubuntu

Build a fully local AI coding agent on Ubuntu using Canonical Workshop and the Qwen3-Coder Inference Snap. In this step-by-step demo, you'll set up an isolated development environment, connect your coding agent to a locally hosted LLM, and run coding tasks without an internet connection. Follow along to recreate the setup on your own machine, using CPU or GPU inference. Chapters.

Your AI Agent Can Act Across Enterprise Systems. Now You Need Delegation of Authority

In 2025, attackers reached the Salesforce data of hundreds of companies without breaking into Salesforce. They used access tokens belonging to an AI chat agent. Google's threat intelligence team counted more than 700 potentially affected organizations, and because the tokens belonged to a trusted app, they carried the attackers past safeguards such as MFA. Enterprises already know how to manage this kind of risk for people.

Shipped: AI dimensions, organized around how your team works

AI Signals adds a standard set of AI dimensions to your dimension picker, plus custom dimensions built from your own data. Not every team needs all of them. The ones you don’t use make the ones you want harder to find. Cleaning that up used to require an engineer to run a script every time an account team needed a change. We identified the bottleneck and automated it, so account teams can manage dimensions themselves and engineering stays focused on product work.

Shipped: Azure cost totals that match your invoice

Azure cost exports sometimes fail with a server error and then succeed on the next try. Some reports cover only part of the month. Large tenants get rate-limited when they request a lot of data at once. Each of these things can leave a gap in your Azure history. You normally find the gap when finance compares the Azure total in CloudZero to the Microsoft invoice.

AI cost per query: how to calculate and optimize it

AI cost per query is your total AI serving spend divided by the number of queries served over the same period. It combines model API charges (input and output tokens), retrieval and orchestration overhead, and shared infrastructure. Most production text queries cost between $0.0005 and $0.02. It's the base unit of AI unit economics, and the number finance needs before any ROI claim holds up.

How a beagle-shaped AI agent ships code to madewithvuejs.com

This is a guest post from Armin Ulrich, a fullstack developer, and founder of placid.app. He also created the MadeWith* network where he shares his projects and allows other developers to share theirs. Two people and one beagle run the project showcase madewithvuejs.com. The beagle is actually an AI agent that we have added to our workflows, but we’re very fond of her by now. Milly is part of the team, scouting for content, building features and sniffing for bugs.

Finding Why Payments Fail with VictoriaLogs Drilldown

Grafana’s Logs Drilldown is a point-and-click way to investigate logs without writing queries. Drilldown lets you break the logs down by service, label, pattern, or any other field, and narrow the selection one click at a time until the problem is in view. It’s a powerful tool, but it only works with Loki. So we built the same experience into the VictoriaLogs data source. We’re happy to announce that the VictoriaLogs data source for Grafana now ships with Drilldown integration.

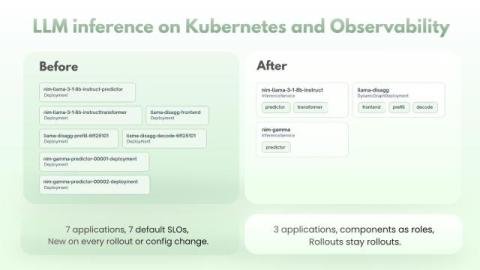
LLM inference on Kubernetes and observability

Running an LLM on Kubernetes is rarely just a Deployment with vLLM in it anymore. A whole layer of frameworks and operators has grown up for it: KServe, NVIDIA Dynamo, Ray Serve, Kthena, llm-d. Each one adds its own custom resource that describes a model deployment, with routing, autoscaling and the split of a model across pods built in, and each one turns that resource into ordinary Kubernetes objects in its own way.