
Operations | Monitoring | ITSM | DevOps | Cloud

SAST vs SCA vs DAST vs IAST: choosing the right scan for the right stage

SAST vs SCA vs DAST vs IAST: a clear breakdown of what each scan finds, when to run it, and how to combine them across your SDLC. Most AppSec teams don't run one type of scan - they run several, at different points in the pipeline, because no single tool sees the whole picture. This article breaks down SAST vs SCA vs DAST vs IAST: what each one actually tests, where it fits in the software development lifecycle (SDLC), and how to combine them without duplicating effort or drowning developers in findings.
How to Use Megaport Storage as a Veeam Backup Target

Learn how to use Megaport Storage as an S3-compatible Veeam backup target for scalable, private, offsite backup storage. Table of Contents A backup is only useful if it can be retrieved when needed. Where backups are stored determines how well they’re protected from incidents at the primary site, how long recovery transfers take, and what it costs to bring the data back.

Every 404 in Your Rails App Might Be Allocating 13 MB

A bot requests /wp-login.php on your Rails app. Rails can’t route it, raises ActionController::RoutingError, and returns a 404. That should cost almost nothing. On a Rails 8.1 app with a few thousand compiled templates, it can cost 13 MB of allocations and 27 ms of CPU. A detailed report on rails/rails#58887 traces the cost to one method, ActionDispatch::ExceptionWrapper#build_backtrace.

How to Cut Cloud Compute Costs Without Rewriting Your Apps

The fastest way to cut cloud compute costs is to stop paying for capacity your workloads do not use. Right-size CPU and memory to real usage, scale idle workloads to zero, and make cost policy a platform default instead of a quarterly review. Control Plane does all three at the platform level: Capacity AI right-sizes running workloads, autoscaling scales idle ones to zero, and customers typically spend 30 to 50 percent less on compute than running directly on AWS, GCP, or Azure.

Tempo 3.1 release: new features for Kafka, TraceQL metrics updates, trace redaction, and more

Building on the major release of Tempo 3.0, Tempo 3.1 is here, delivering community-contributed Kafka client improvements, query-based trace redaction, sampling-aware TraceQL metrics, and more. Together, the updates in 3.1 make it easier to operate Tempo, get accurate insights from your trace data, and investigate issues more efficiently. You can continue reading and check out the video below to learn more about the latest features.

MTTR Is Not a Time Problem. It Is a Context Problem

Your Mean Time to Resolution (MTTR) has likely stayed flat for three or four quarters. The investment was real: scheduling tools, dispatch optimization, new training modules, and more technicians. Operations reviews still dissect response time, travel time, and wrench time. The metric still refuses to move. Most field service leaders measure MTTR from the start of the repair to the moment the asset returns to service.

AI cost allocation: how to attribute AI spend by team, product, and customer

AI cost allocation is the practice of attributing every dollar of AI spend to the team, product, feature, or customer that generated it. That spend includes API tokens, GPU compute, per-seat tools, and shared infrastructure. It's harder than cloud allocation because AI spend arrives untagged, spans vendors, and pools in shared resources. Four methods cover most cases: tag-based, key-based attribution, proportional split, and usage-telemetry.

Shipped: One CloudZero for everyone, starting October 1

On June 3, we made the new CloudZero experience the default for every customer. Since then, we’ve shipped around 30 improvements a week: side-by-side period comparisons in Explorer, budgets you can create and edit right in the app, threshold alerts on dashboard tiles, and Monitors, which flags AI and cloud spend that moves outside its normal pattern and shows you what changed. Pages load 28 to 61% faster. JavaScript execution is 85% faster.

IT Service Continuity Management: How to Build an ITSCM Plan

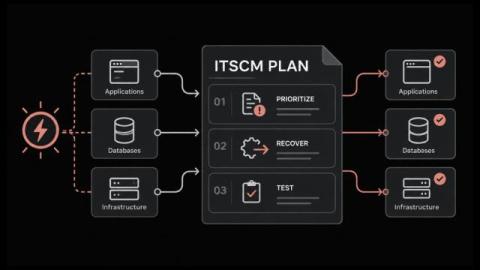
Most IT teams have a recovery plan somewhere. It was written for a disruption that has not happened yet, and tested less often than anyone admits. The gap rarely sits in the technology. Nobody agreed which services come back first, or how fast. There was time to settle that calmly, and it went unused. IT service continuity management is the ITIL practice that settles those questions in advance. In this blog, you will: By the end you will know what belongs in an ITSCM plan and who has to agree to it.

How IT Infrastructure Management Keeps Services Reliable and Costs Predictable

When a business application slows down, how fast can your organization trace the cause to a server, a network link, storage or a cloud instance? Often it comes down to who's on call that day, since asset, observability and change data are scattered across separate systems. Engineers then check each tool one at a time while customers wait and the cost of the outage grows. IT infrastructure management solves this by keeping asset records, health data and change history in order before an incident starts.