Operations | Monitoring | ITSM | DevOps | Cloud

Sentry's Flutter SDK 10.0: Streaming Traces and More Accurate Crash-Free Rates

Sentry’s Flutter SDK 10.0 makes streaming traces the default and changes how unhandled Flutter errors affect Release Health. Errors that leave your app running no longer mark the session as crashed, so your crash-free rate better reflects actual app crashes. The release also gives app startup its own trace on Android and iOS, simplifies logs and metrics setup, expands Dio network error capture, and respects Flutter’s sensitive-content markings in Replay and screenshots.
How to Add a Neocloud to AWS or GCP Without Running a Second Stack

There is no single best neocloud for AWS or GCP teams. The right one depends on the workload. Bursty fine-tuning and batch jobs reward flexible billing and low hourly rates. Always-on inference and agents reward capacity you can keep plus a second place to run, and data-heavy pipelines reward cheap data movement.

How we accelerated code review in a large monorepo using Agentic Pipelines

Last quarter, our AI reviewer told a developer who was fixing a CSS bug to rethink how their component fetched data. The comment was well written and confidently worded. It was also about code they hadn’t touched. That’s what tends to happen when you hand an agent every team’s review guidelines at once.

Go from alert to post-incident review with Grafana Cloud IRM and AI

You’ve got 10 minutes before your next meeting when your phone starts ringing. You’re being paged because the frontend is erroring with failed API requests. You open one tool to see what fired, then another to figure out what’s going on. You message a teammate in Slack to see if they’re noticing the same thing. That’s a lot of context switching, and it’s still how a lot of teams' incident response works today. Opening another tool and catching someone up takes time.

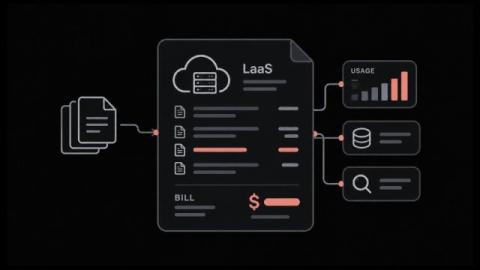
Logging as a Service (LaaS): What It Costs and When It Fits

Logging as a Service moves your log management to a provider. They collect, parse, store and search your logs for a monthly fee. The fee is where it goes wrong. Providers meter five different things, and the one written into your contract decides whether ordinary growth doubles your bill. In this blog, you'll see: By the end you'll know which meter your workload lands on. Logging as a Service is a cloud-delivered model for collecting and searching logs.

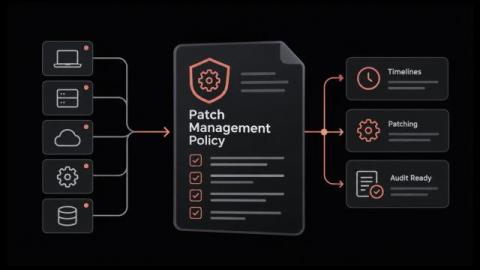
What a Patch Management Policy Should Contain to Keep Systems Secure and Audit-Ready

Who decides how fast a critical patch goes out, and who signs off when a production server can't be restarted? For many IT groups, the answer is a mix of one senior admin's judgment, an old ticket and a shared spreadsheet. It holds up fine right until an auditor asks for proof, or that admin leaves. A written policy replaces that guesswork with rules people have agreed to. Owners are named, deadlines are fixed, and there's a plan for the system that can't be patched on time.

Best Cloud Storage UK: Affordable, Secure, and Private Options

If you’re looking for alternatives to US tech giants spying on your data and need a secure, private cloud storage solution for your files, then these best cloud storage for UK customers offer the best alternative to major cloud companies, with the added advantage of extra features, and no more subscriptions with lifetime options.

Stop Letting Deployment Approvals Slow Down Your Releases

Learn how to streamline deployment approvals with Harness CD native approval steps and configurable policies to reduce manual effort, improve consistency, and accelerate releases. Approvals shouldn’t cost you a shift. With Harness, the approval step lives inside your pipeline, so you get sign-off without the waiting and the glue code.

Deployment alerts: know when a renewed certificate doesn't land

Renewing a certificate is the easy part. Getting it onto the server is where automation breaks. Somebody rotates the API token on the firewall. A service account password expires. A VM gets rebuilt and the agent never comes back. The certificate renews right on schedule, the deployment fails, and the server keeps serving the old certificate until it expires. Renewed and deployed are not the same thing.

Honeycomb Adds Another AWS Competency: Resilience Technology

We're excited to share that Honeycomb has achieved yet another Amazon Web Services (AWS) Competency—the Resilience Technology Competency—which recognizes our ability to help customers detect, investigate, and recover from failures in production systems running on AWS. While receiving the competency designation is a fantastic recognition of the capabilities of the Honeycomb platform (we also received one in Financial Services earlier this year), it's ultimately not the point.