Operations | Monitoring | ITSM | DevOps | Cloud

Try Qovery on Your Laptop: Ask Your Coding Agent, Get a Running App

The Qovery agent skills now create a free local Kubernetes cluster in Docker when your organization has none, then deploy your project to it. One prompt in Claude Code, Cursor or OpenCode, no cloud account, no credit card. Measured: 4 min 43 s for the cluster, 2 min 40 s to build and deploy a GitHub repository. Romaric founded Qovery to make Kubernetes accessible to every engineering team. He writes about platform strategy, developer experience, and the future of cloud infrastructure.
How eMudhra, TWCA, and GoDaddy incidents compare against other CAs

Three CAs had very different bad weeks this fall. eMudhra lost a root and quit. GoDaddy had to replace 403,643 certificates over a policy document. TWCA revoked 82% of its certificates over serial numbers. TWCA and eMudhra both failed from a lack of randomness. eMudhra’s private keys had so little that anyone could compute them. TWCA’s CA certificates have serial numbers with 24 random bits where the rules require 64.

6 Best Code Review Platforms for GitHub and Jira (2026)

Your team runs on GitHub for code and Jira for planning. But when it comes to code review tools, those two worlds rarely talk to each other. Pull requests pile up on one side while issues stall on the other, and reviewers lose time switching between tabs to piece together context. GitKraken gives you a connected code review workflow that bridges GitHub and Jira, so your team spends less time chasing context and more time shipping.

Conductor is joining Meta. What that means if you run parallel agents

On November 4, Conductor announced it’s joining Meta. If you run your agents in Conductor, you probably saw the post that morning. I know I saw it when my coworkers started sharing the link in Slack. If Conductor was your main tool, this kind of sucks. You didn’t plan to go shopping for a new one this month, and 2 weeks to get off Cloud is pretty tight, especially if you built scripts around it.

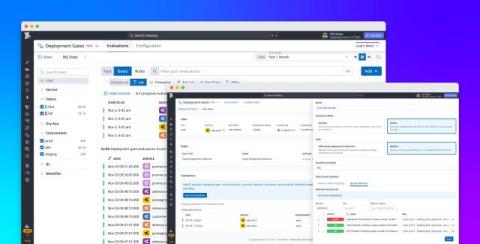
Catch incidents and pause faulty deployments automatically with Datadog Deployment Gates

As AI-assisted development helps teams create and ship more code, engineers need to check a growing volume of changes under real production conditions. Even code that passes testing can introduce errors or slowdowns in production, so early detection is essential to protecting customers. Automating those health checks helps teams keep pace by reducing the time engineers spend watching dashboards.

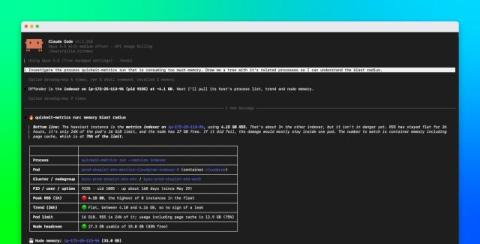
Investigate Kubernetes health and processes with the Datadog MCP Server

When investigating issues with a Kubernetes service, SREs and platform engineers need to understand what’s happening across its supporting infrastructure. For example, is a process still running? Did it restart? Is the scheduler struggling to place pods? Finding the answers to these questions often requires engineers to search process inventories, examine resource metrics, and query Kubernetes control plane telemetry.

Run cost-effective, always-on agents to monitor your environment: the engineering behind Watchers

Alert rules are great for the failures you can predict, but they fall short on the ones you can't. With the advent of modern AI, you might think the solution is to swarm your stack with agents that monitor every last detail, but that can quickly lead to astronomical bills. And those are the gaps Watchers fill: catching what alerts miss while keeping costs in control. Generally Available as of ObservabilityCON 2026, Watchers are always-on agents in Grafana Assistant.

How a broken release name overloaded our symbolication database

When a JavaScript error reaches Sentry, the stack trace points at minified code. Sentry finds the source map that was uploaded for that build to be able to show you the original file and line. Source maps are uploaded in artifact bundles. There are two ways to find the right one: Symbolicator, our open-source symbolication service, does the lookup when it processes an event.

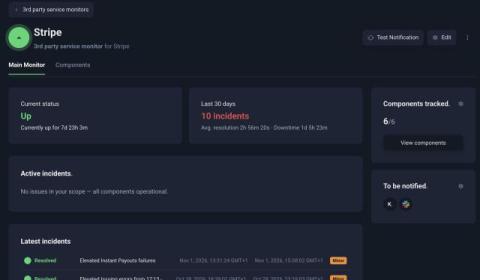
Third party service monitoring is now in the API, MCP and CLI.

We’re happy to announce that you can set up Third party service monitoring from the UptimeRobot API, MCP server and CLI too, and get alerted when a service your product depends on has an outage. Add a provider from your deploy pipeline, ask your AI assistant whether Stripe had an incident last night, or check a provider’s status from your terminal.